
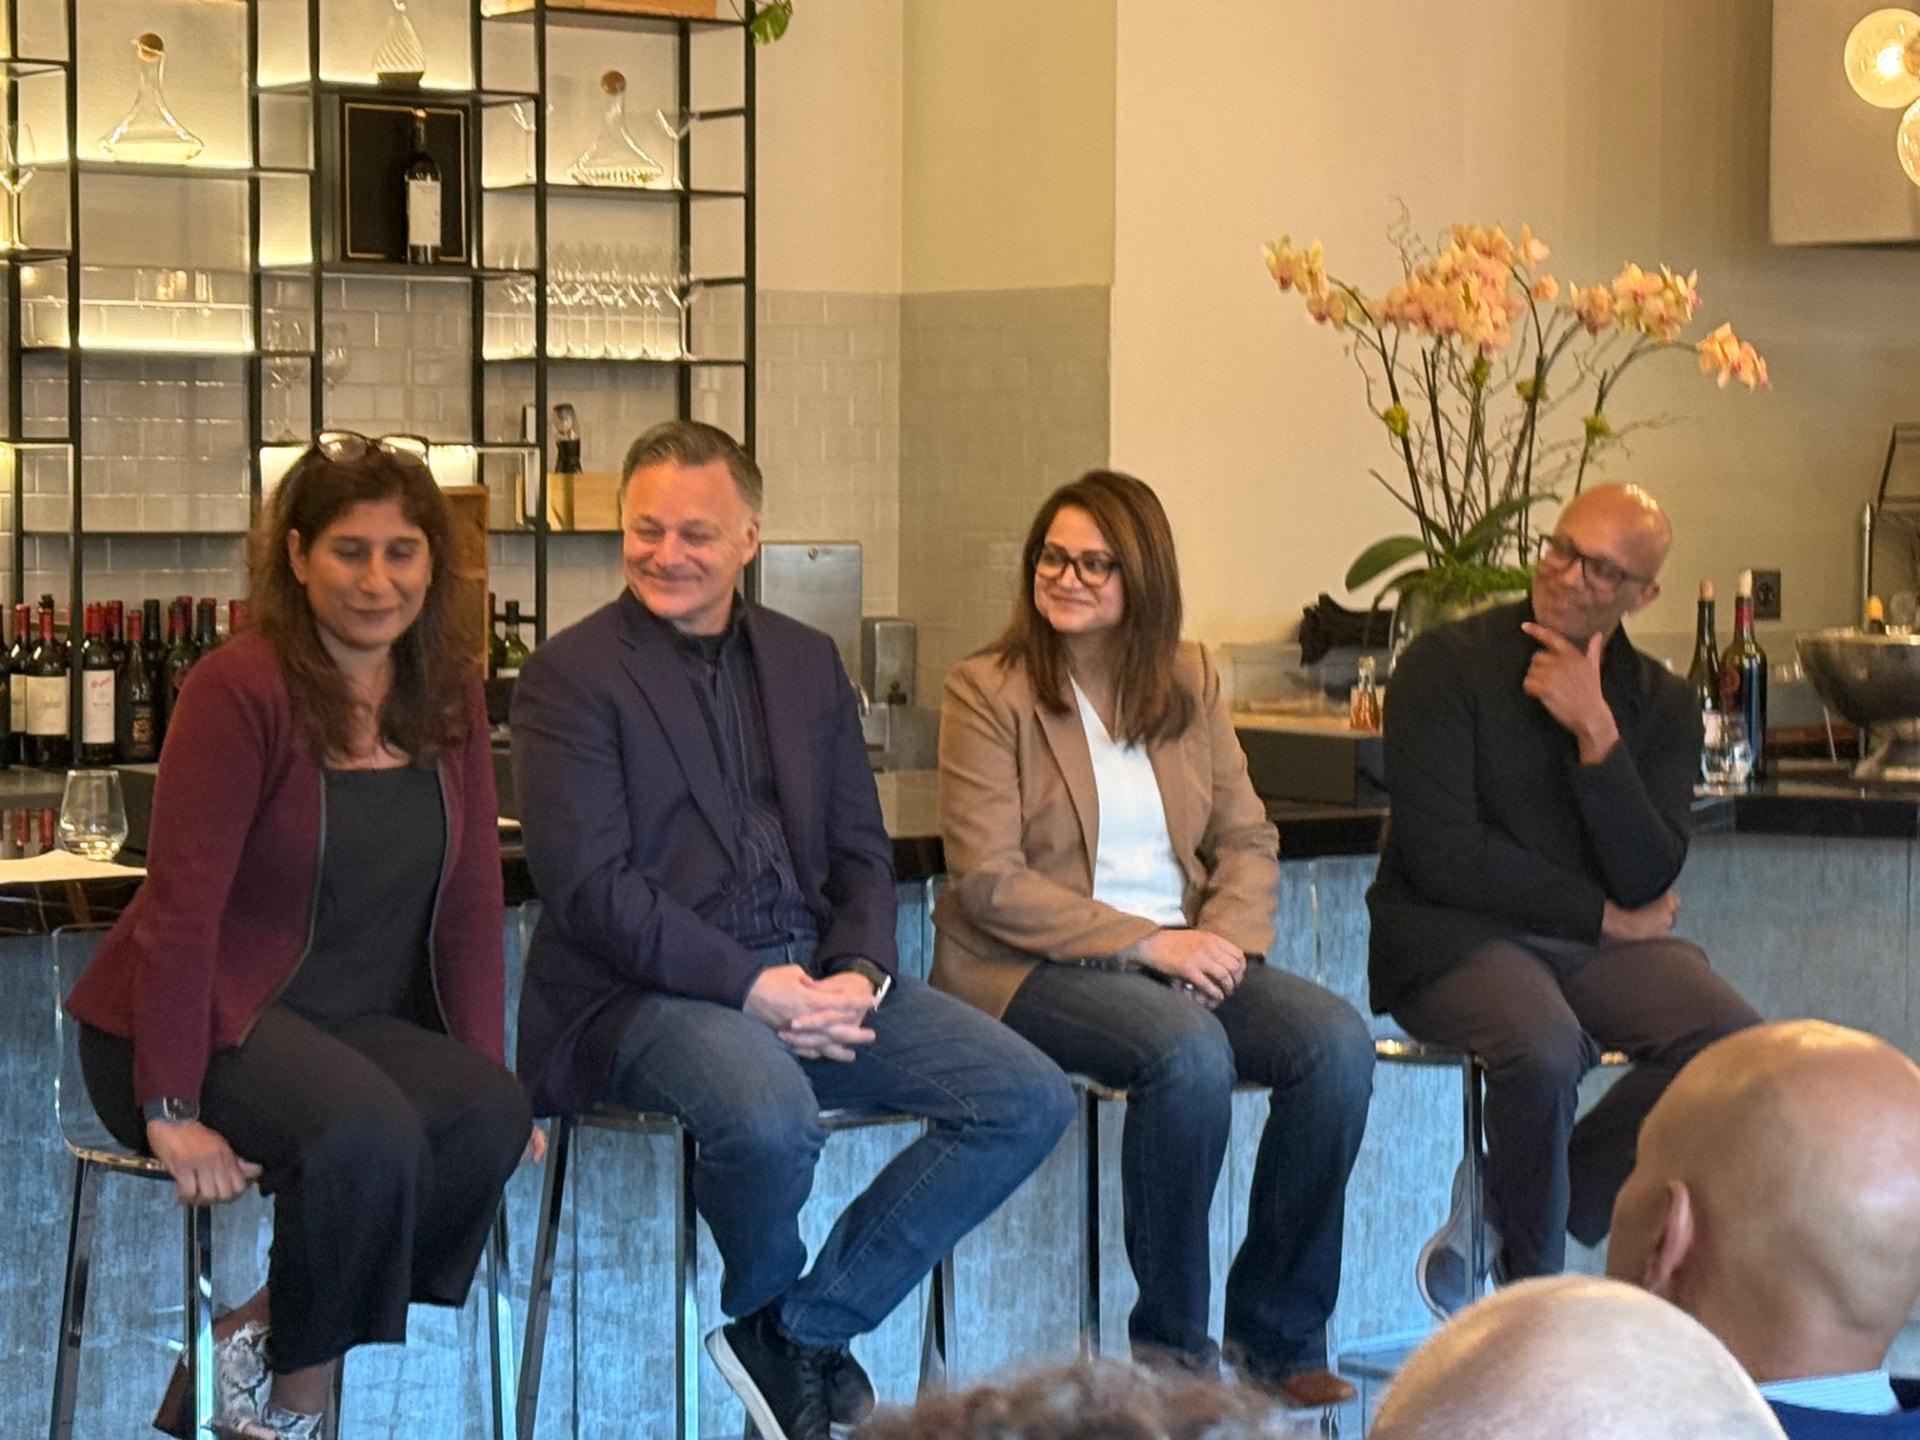
SVEN, the Silicon Valley Executive Network that Brian Reynard founded twenty years ago, opened a new monthly series in Mountain View on November 10. The format pairs CXOs with AI practitioners, and the first panel brought together four people working in very different places.
- Charu Madan, EVP BD and Partnerships, Navina (moderator and panelist)
- Bhawna Singh, CTO, Lightspeed Commerce
- Praveen Mandal, Co-founder and CEO, JoulesAI
- Tobias Yergin, Co-founder, Baser Potential
Most of the evening dealt with agents in the enterprise. The newer material came at the edges of the conversation, where AI meets batteries, power grids, store floors and the physical limits of compute. That material, along with what the panel said about how investors are behaving, is the focus here.
Physical assets have no undo button
Praveen's company, JoulesAI, orchestrates energy assets such as batteries and solar to meet each customer's cost and reliability objectives. He described the problem with dropping a language model into that loop. If the system dispatches a battery on a bad call, the charge is gone. A software team can roll back a release, but nobody can roll back a drained battery.
His team has published a paper arguing that an autonomous energy grid needs contextual guardrails, meaning rules that allow or block each decision based on the state of the system at that moment. Praveen's point was that physical systems need that judgment enforced in the architecture, outside the model.
The same requirement appears across physical AI, from warehouse robots to vehicles to clinical devices. When an action cannot be reversed, the proof that the action is safe has to come before the action, and the guardrail has to be designed for the asset it protects.
The grid has slack
The panel took on a question many people in the room were thinking. AI is a large and growing consumer of electricity, utilities are building new generation to keep up, and residents are protesting rising prices. Will AI ever give some of that back?
Praveen's answer turned on how the grid was built. It was designed for peak load, so on average about half of its capacity goes unused. AI training and AI inference have different workload profiles, and both can be scheduled with more flexibility than a household or a factory. EV charging depots offer another example, with stations sitting idle while power is still provisioned for them. Flexible load matched to flexible supply is where the efficiency gains live, and orchestration software that operators trust is what captures them.
Tobias offered a harder framing. He argued that society may have to accept short-term costs, such as a few cents more per kilowatt-hour, in exchange for what the technology could deliver. Nobody on the panel claimed that trade was settled, and grid capacity is becoming a gating factor for both AI deployment and physical AI at scale.
Twenty watts
An audience question about data center supply, and whether edge computing changes the math, drew one of the more striking comparisons of the evening. Praveen noted that the human brain runs on about 20 watts, while a single high-end GPU draws roughly a thousand. The body adds sensors, perception, learning and decision-making to that budget at a fraction of the power.
His conclusion was that bigger and faster hardware will continue, but the larger opportunity lies in fundamentally more efficient computing. He pointed to quantum computing as it moves toward real applications, and to early startups combining living neurons with semiconductors in biological computers.
Praveen also argued that language models are flattening out on complex reasoning. In his view, the next step runs through world models that learn the physics of the world from large volumes of sensor data. Those models would give machines a footing for the reasoning physical tasks demand.
Intelligence at the edge
Two panelists gave concrete examples of moving AI closer to where the work happens.
Tobias described an architecture he built while running AI research at Walmart. A model of roughly 3.8 billion parameters ran on the store associate's phone, a 70-billion-parameter model ran on a server in the back of the store, and a frontier model handled anything neither could. A router chose the tier by use case, cost and how fast the answer was needed. Latency drove much of the design, since an associate helping a customer cannot wait two minutes for a reply. So did cost, because sending every query at that scale to a frontier model would drain the budget quickly. The phone's sensors shaped the answer too. If the device registered about 65 decibels in a loud part of the store and the associate was hearing-impaired, the system delivered the response as subtitled video. Store data stayed inside the store.
Bhawna described edge work from her time at Okta. Authentication is a heavy round trip to the core, so her team handled anonymous users at the edge, which helped them scale with OpenAI tenfold in nine months. In her view, every request the edge can settle protects the core infrastructure and lowers its cost, though edge hardware still lacks the storage for full authentication.
For anyone building or funding edge AI silicon, those two examples describe the demand side clearly. Enterprises want small models on devices, mid-size models on site and a router deciding between them, for reasons of latency, cost and data control.
Wisdom needs a body
Late in the evening, the audience asked what remains fundamentally human. Tobias drew the distinction between intelligence and wisdom. Models have intelligence. Wisdom comes from experience, usually physical interaction, and current models do not have it. In his view, the path there runs through robotic systems with dense sensors that keep learning in the field and update their weights continuously, and that path will take considerable time.
A panelist added an unexpected angle from drug discovery. A peptide researcher in his circle treats model hallucinations as a source of ideas his team had not considered. In a domain where every candidate gets tested in the lab, a wrong answer can still open a new line of inquiry.
What investors are doing differently
The panel was asked about fundraising, and the answers were candid.
One panelist said there is more capital available than before, and that fundraising still moves in waves. The harder problem for investors is sifting real AI companies from the noise when every company uses the label.
Another said adding AI to a company's name no longer guarantees anything, because diligence has caught up. Some VCs she knows now use AI tools to rebuild a startup's product before investing. If they can get close quickly, they pass.
Praveen was skeptical of a benchmark now circulating in Silicon Valley, ten people reaching $100 million in revenue within three years. He asked how many such companies anyone could actually name, and called the metric directional at best.
An audience founder added the other half of the picture. Building has become much easier, while reaching customers has become harder, particularly in the mid-market, where buyers cannot find specialized services even when they need them.
For deep tech founders, the takeaway is that a defensible company needs something a coding agent cannot reproduce over a weekend. Physical assets, proprietary sensor data, hardware and hard-won domain access are much harder to copy than an application layer.
The physical world sets the pace
Software can iterate weekly, and the frontier models now ship faster than most users can absorb. Batteries, grids, robots and stores move at the speed of proof. The useful insights came from the people working where those two speeds meet. Their questions about guardrails, power and edge architecture will shape which physical AI companies earn trust and capital over the next few years.
Thanks to Brian Reynard and SVEN for hosting, and to Charu, Bhawna, Praveen and Tobias for the conversation.
By Larry Chao, Sovereign Pivot